The Home Screen
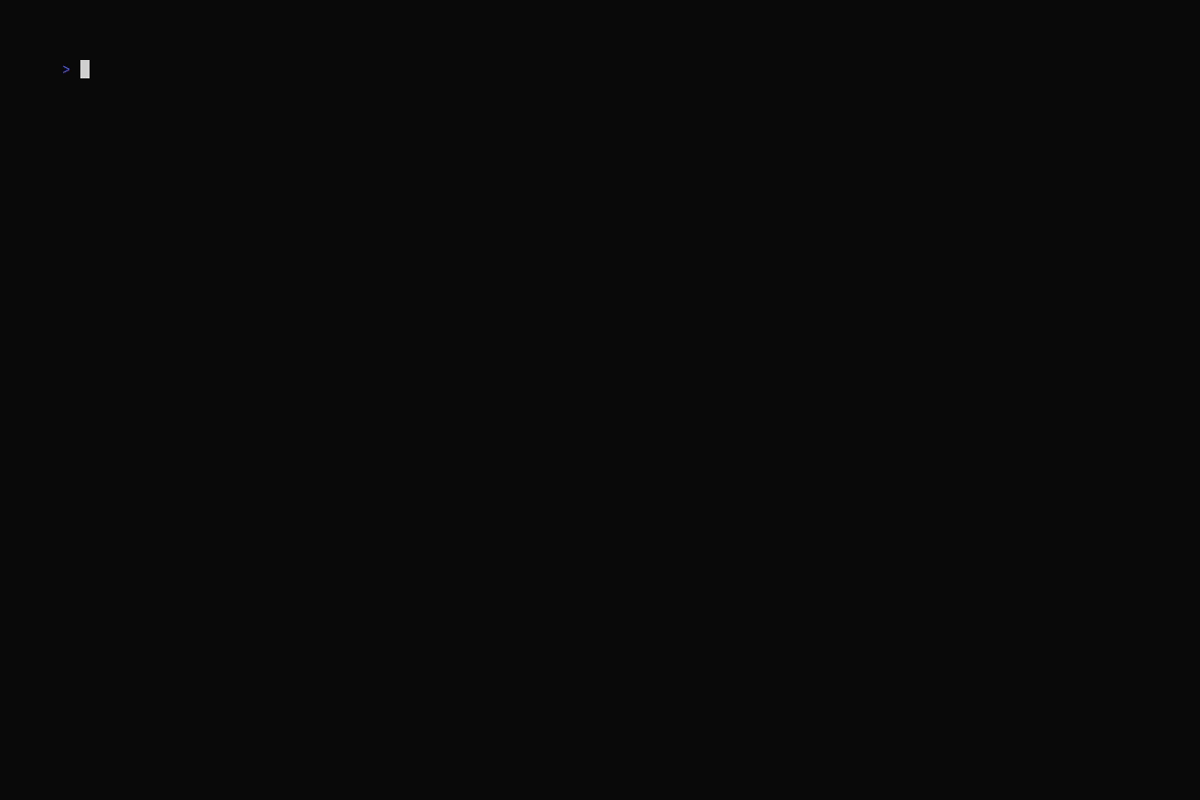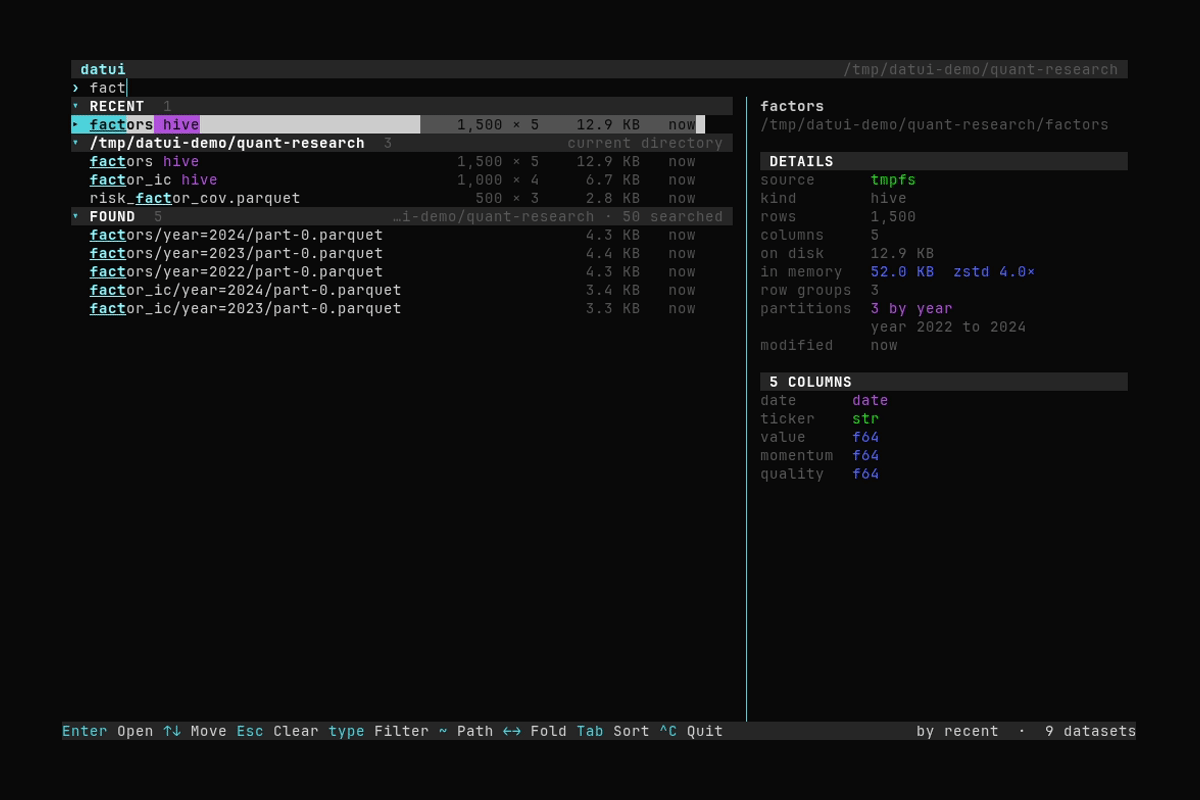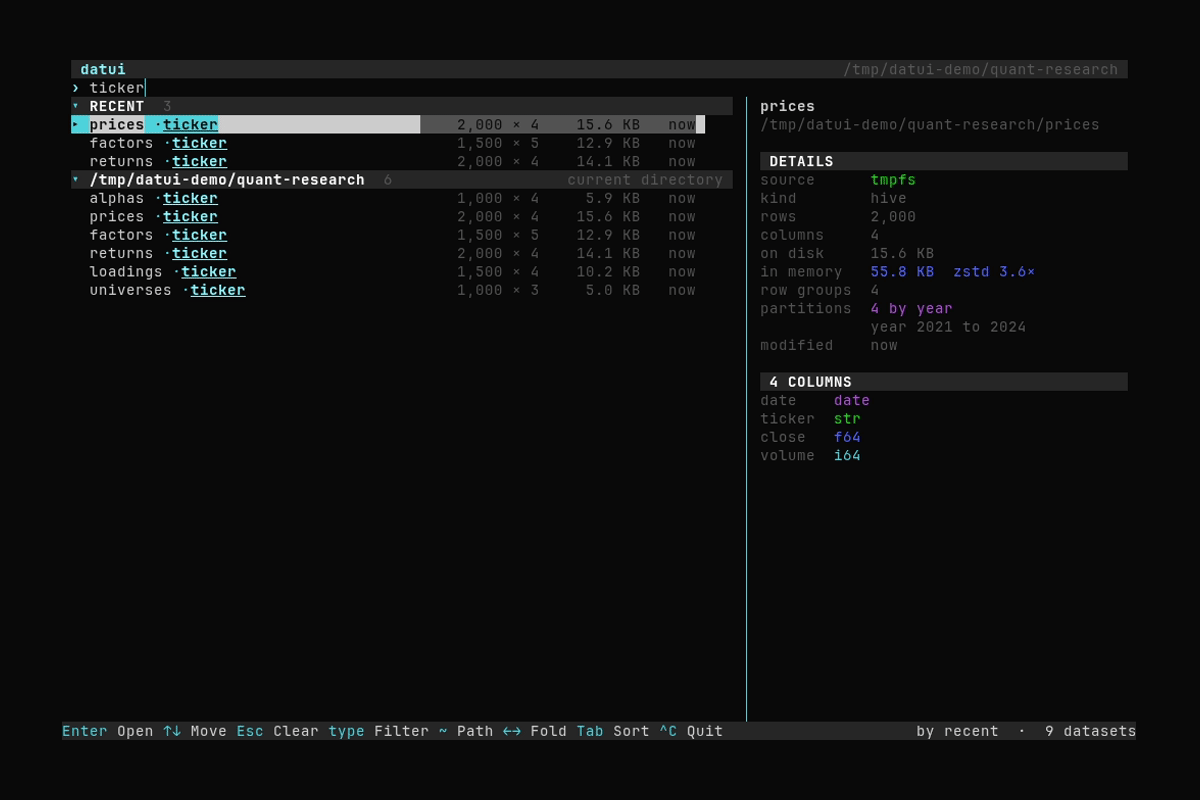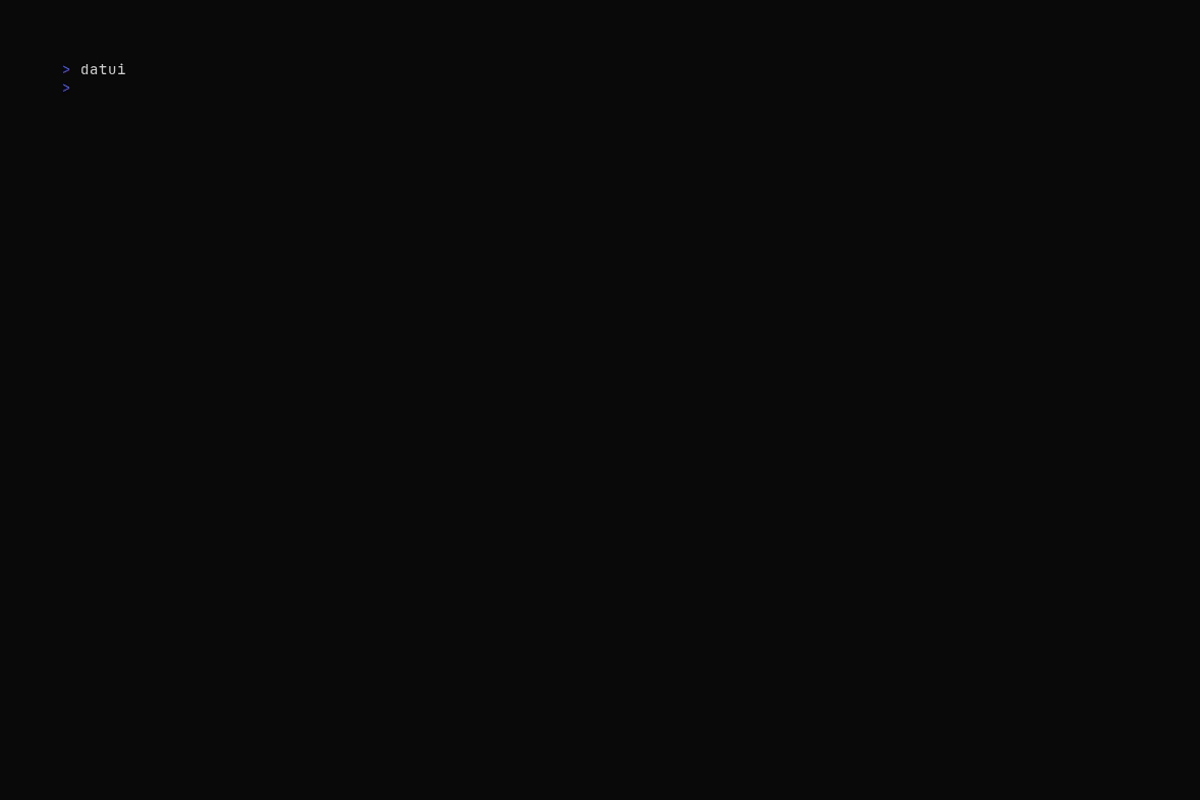
Run datui with no arguments to open the home screen: a list of datasets, with
what each contains shown before you open it. Ctrl+O returns
here from anywhere.
 datui                                                         ~/work/analysis
› ▏  type to filter
▾ RECENT
▸ sales                          hive      2.4M × 18    340 MB    2d
  customers.parquet                          89k × 12     4 MB    1w
▾ /mnt/data                                        network · configured
  events                         hive       1.1M × 9    120 MB    3h
  lookup.parquet                              980 × 4     8 KB    2mo
▾ ~/work/analysis                                     current directory
  raw_export.csv                                        1.2 GB    3h
  notes/                         dir
Enter Open  ↑↓ Move  Esc Quit  type Filter  ~ Path  ←→ Fold  Tab Sort
Keys
| key | action |
|---|---|
| ↑ ↓ / k j | move |
| ← → / h l | collapse / expand the section |
| Enter | open the dataset, enter the directory, or fold the section |
| type anything | filter by name (fuzzy: sal matches sales) |
| ~ | type a path directly; Tab completes it |
| Backspace | delete a filter character, or leave a directory |
| Tab | cycle the sort: default, size, modified, rows |
| Delete | forget the highlighted entry (under RECENT only) |
| Shift+Delete | forget every recent entry, after confirming |
| Ctrl+U | clear the filter |
| Esc | back out one layer: clear filter, leave directory, return to your data, quit |
| Ctrl+C | quit |
| Ctrl+O | return here from anywhere, including during a load |
q does not quit here — plain characters go into the filter. The control bar shows what Esc will do next.
Where the list comes from
The list is grouped by root — a directory datui looks in. Sections appear in this order:
| # | section | source | shown when empty |
|---|---|---|---|
| 1 | RECENT | datasets you have opened, most recent first | no |
| 2 | the current directory | where you launched datui | yes |
| 3 | a configured directory | [data] directories, in the order you list them | yes |
| 4 | directories of recent datasets | added when you open something | no |
| 5 | ELSEWHERE | desktop places | no |
Where you are comes first: a directory holding sixty recently-opened files would
otherwise push the place you just cd’d into off the screen.
A directory reached more than one way appears once, under the earliest of these that names it.
Sections fold with ← and →. A folded section shows how many rows it is hiding, and stays folded until you expand it or restart datui.
Filtering keeps the grouping, so a match always shows which root it came from.
Reaching somewhere new
~ opens a path input, and Tab completes what you type — as far as the candidates agree, and no further. A lone directory gains its trailing slash, so a second Tab steps into it. When several match, the count is shown.
Opening something this way adds the directory holding it to the list, so a place only has to be found by hand once.
Adding a root
Name it in your config. This is the only explicit way, and the only one that
keeps a place listed when it is empty or its mount is down (it shows as
unavailable rather than disappearing):
[data]
directories = ["/mnt/data", "~/datasets", "$WORK/warehouse"]
~ and $VAR are expanded.
Otherwise roots accumulate on their own: opening a dataset adds the directory holding it, so somewhere on a mount only has to be found by hand once. Press ~ to type a path, open something, and the place is listed from then on. Roots gathered this way disappear again when they hold nothing.
Desktop places
datui reads freedesktop’s recently-used.xbel — written by file managers and GTK
applications — and offers the directories it mentions. Never the file names:
those places are listed unexpanded under ELSEWHERE, and their contents appear
only after you press Enter.
  ELSEWHERE                        opened elsewhere · press Enter to look
    ~/Downloads/                 dir
datui reads that file, never writes to it, and sends nothing anywhere. To ignore it:
[data]
use_desktop_recents = false
Searching below where you are
Typing filters the rows already on screen. It also starts a recursive search of the
working directory, and datasets found below it appear in a Found section
under everything else.
The walk runs once, in the background, the first time you type. Every keystroke after that filters the result in memory, so the search gets no slower as you narrow it. Nothing is walked if you never type — launching datui, pressing Enter on a recent dataset and leaving costs nothing.
How matching works
datui scores fuzzy matches the way fzf does, using fzf’s own constants and its
path scheme. That is deliberate: anyone reaching for a fuzzy filter already has one
calibrated in their fingers, and a finder that ranks differently feels broken rather
than different. It is the same scoring fzf, fzf-lua, Telescope with
telescope-fzf-native, and neovim’s snacks.picker all use.
What that means in practice:
| behaviour | example |
|---|---|
a match after / or _ beats one mid-word | sales prefers a/b/sales.csv to zzsalesz.csv |
| consecutive beats scattered | abc prefers abc.csv to a_b_c.csv to axbxc.csv |
| a match in the file name beats one in a directory | sales prefers archive/old/sales.csv to sales/2024/report.csv |
| the best alignment wins, not the first found | revdetail marks revenue_detail, not the re in warehouse |
| ties go to the shorter name | sales prefers sales.csv to sales_by_region_and_quarter.csv |
That last-but-one row is the one people notice. A left-to-right greedy matcher would
underline re inside warehouse; every mainstream finder tries every starting
position and keeps the best-scoring one, and so does datui.
The characters your filter matched are underlined in each row, so you can see why a result is there — useful when a fuzzy match lands somewhere you did not expect. A row that matched on a column rather than its name has the highlight on the column note instead, since marks scattered over an unrelated filename would read as the filter having gone wrong.
Results are named by their path below the search root, because three files called
sales.parquet are indistinguishable otherwise:
Found   ~/work/analysis · 954 searched
  europe/q3/sales.parquet          12.4 MB   1.2M rows   3 days ago
  americas/q3/sales.parquet         9.1 MB   890K rows   3 days ago
The heading says how much was searched, and says when the walk stopped early —
partial · out of time, partial · too many, partial · too deep. A search that
quietly returned less than the truth would be worse than no search, because “it is
not here” is something you act on.
What is skipped, and why not .gitignore
datui does not read .gitignore. People gitignore data directories precisely
because the data is too big to commit — which is the same reason they want to open it
in datui. Measured on datui’s own repository, honouring .gitignore hides 38 real
test datasets while hiding 69 files of virtualenv noise. Wrong in both directions.
The noise is handled structurally instead:
| rule | effect |
|---|---|
| hidden directories are skipped | .git, .venv, .tox, the caches |
| a fixed name list | node_modules, target, build, dist, vendor, site-packages, __pycache__, venv, env |
| filesystem boundaries are not crossed | a search never wanders onto a mount |
| symlinks are not followed | no loops, no escaping the tree |
The name list matters more than it looks: node_modules and site-packages are full
of .json, which datui can open, so without it every package manifest on the machine
is a search result. In datui’s own tree the list cuts the entries examined from 15,177
to 306 and finds exactly the same 80 datasets.
Not crossing filesystems is the limit that keeps the home screen fast. It is what
stops a walk from descending onto a network share, and on a machine using autofs, from
mounting one merely by looking at it. The cost is that data on a mount beneath your
working directory will not be found by the search — turn cross_filesystems on if
that is where your data lives and you know the mount is fast.
Tuning it
[data.search]
enabled           = true
max_depth         = 8
max_results       = 20000
time_budget_ms    = 1500
cross_filesystems = false
follow_gitignore  = false
skip       = ["node_modules", "target", "build", "dist", "vendor",
              "site-packages", "__pycache__", "venv", "env"]
skip_extra = []
extensions = []
- skip replaces the default list entirely; skip_extra adds to it, so putting one directory out of reach does not mean restating the other nine.
- extensions empty means every format datui can open — which includes
jsonandtxt. Narrow it to["parquet", "csv"]if a source tree is too noisy. - time_budget_ms is what makes a cold or enormous tree degrade to partial results rather than to a wait.
Details
rows, columns and size say what a dataset is. None of them say what reading it
will do, and the difference is large: 200 MB of zstd-compressed Parquet is two
gigabytes once open, and two gigabytes over a hotel-wifi NFS mount is a different
afternoon than two gigabytes on tmpfs.
The preview pane shows both, in one list:
 DETAILS
source      nfs4
kind        hive
rows        412M
columns     38
on disk     184 MB
in memory   1.4 GB  zstd 7.6×
row groups  12
partitions  1,460 by date, region
            date 2021-01-01 to 2024-12-31
modified    3 days ago
| line | where it comes from | why it matters |
|---|---|---|
source | the kernel’s mount table | nfs4, cifs and fuse.sshfs fail in three different ways, and none behaves like tmpfs |
in memory | the Parquet footer | what it will occupy, as against what it occupies on disk |
row groups | the Parquet footer | one enormous group cannot be read in parallel or skipped through; a thousand tiny ones cost more overhead than they save |
partitions | directory names | the shape of a partitioned dataset, knowable without opening a single file |
None of it costs an extra byte of the dataset. The mount table is a kernel-generated file — reading it cannot block on the filesystem it describes, which is why it is safe to ask about a share that has stopped answering. The compression and layout figures come out of the same footer datui already reads for the row count. The partition layout is directory names.
source is the filesystem’s own name and nothing else — colour carries the warning,
so a remote or object-store source stands out without a sentence explaining that a
network is a network. Sections name the filesystem too, so nfs4 · recent replaces a
bare network.
A dataset directory reports no size rather than the size of its own inode. Two hundred
bytes is what stat says about a directory holding a terabyte, and printing it reads
as an answer.
Sorting
Tab cycles how rows are ordered inside each section. The control bar names the order currently in effect where the cursor is:
- the default suits each section —
recentunderRECENT,nameunder a directory size,modifiedandrowsorder every section the same way
Rows with nothing to sort by go last rather than counting as zero, so size does not
open with a page of datasets whose size has not been read yet.
While a dataset is loading
Pressing Enter leaves this screen immediately, and what replaces it is the load in progress, not the dataset you had open before:
                            ⣷  Caching schema…

                              events.parquet
                       ~/data/events.parquet   120 MB
The phase names a real step — scanning the input, caching the schema, filling the first buffer — so a load that is slow still shows where it has got to. Ctrl+O abandons it and comes back here; Esc from here then returns you to whatever was open before, which is untouched.
When a dataset will not open
datui shows what went wrong and returns you to this screen with the reason, so the next choice is one keystroke away rather than a dead end:
› corrupt▏ …parquet: 'parquet scan': the file must end with PAR1
Network locations
The home screen never reads a network location on the thread that draws it. An
unreachable NFS share does not fail, it blocks — for seconds on a soft mount, and
indefinitely on a hard one, which is the default and cannot be interrupted. So a
root on a network filesystem, and any s3://, gs:// or https:// path, is
recognised from its name and the mount table alone, without being reached for.
The consequence is that datui starts at the same speed whether the network is there
or not. A remote root appears immediately, marked network · checking, and is
listed in the background:
▾ /mnt/data                                        network · configured
  events                         hive       1.1M × 9    120 MB    3h
▾ s3://bucket/warehouse                         network · checking
A remote dataset datui has measured before shows its counts and columns straight
away, from the cache. One it has not shows its name and nothing else until the
listing arrives — size, counts and type all require reading it. A location that
never answers is marked unavailable and not retried.
Remembered facts for a remote dataset are used without re-checking, since checking
means a stat on a path that may not answer. A stale row count is a better answer
than an empty one for the datasets that are hardest to reach. Local datasets are
verified against size and modification time, and re-measured when either changes.
Object-store and HTTP URLs are recorded in RECENT like any other path, and are
worth having there: s3://bucket/warehouse/events/year=2024 is the sort of path
worth not retyping.
Finding a dataset by its columns
Typing into the filter matches dataset names and column names. Searching
customer_id finds every dataset that has such a column, with the match shown
against the row:
› customer_id▏
▾ RECENT  2
▸ sales                 ·customer_id      2.4M × 18    340 MB    2d
  orders.parquet        ·customer_id        89k × 12     4 MB    1w
A name match always ranks above a column match, so typing a dataset’s name still finds the dataset.
Column names come from the Parquet footer datui already reads to get row counts, so this costs nothing extra — and they are remembered between runs, so a search works immediately on a cold start without reading anything.
Columns are known for Parquet datasets that have been measured at least once. Formats that need a scan to read a schema are matched by name only.
What counts as a dataset
| on disk | shown as |
|---|---|
customers.parquet | one dataset |
sales/year=2024/…, sales/year=2025/… | one row, sales · hive |
exports/ holding several matching Parquet files | one row, exports · multi |
| a directory of source code with a stray CSV in it | a directory to enter |
| a network path not yet listed | openable, with no type shown until it is |
Reading the columns
sales          hive     2.4M × 18     340 MB     2d
                        rows × cols   size       last modified
Row and column counts come from Parquet footers, summed across at most 64 files for
hive and multi-file datasets. A dataset larger than that shows ? × 39 — its width
is known, its length is not. Formats that need a scan to count rows (CSV among them)
show neither.
Rows are measured a few per frame, and only those on screen, so a directory of large datasets appears immediately and the counts fill in. Measurements are kept for the session.
The preview pane shows the full schema for Parquet datasets, each type in the colour the table will use.
Loading
Ctrl+O works while a dataset is loading; scanning runs off the interface thread.
Leaving a load abandons it rather than cancelling it. The scan runs to completion in the background and its result is discarded — it cannot overwrite whatever you open instead, but it does use CPU until it finishes.
Narrow terminals
The screen adapts rather than truncating. Below roughly 100 columns the preview pane yields so the list keeps its size and shape columns, and below about 56 those columns go too. The control bar is ordered so that if it has to be cut, what survives is how to open, move and leave.
What datui remembers
Two things, both in the cache directory:
- Recently opened paths, so the list has somewhere to start.
- What it measured — row and column counts, and column names — each stamped with the size and modification time it was taken from, so a dataset that has changed invalidates itself.
Delete forgets a single entry under RECENT — for an experiment, a file
that would not open, or something you would rather not have on screen. Only under
RECENT: a row inside a directory is a real file, and datui does not delete files.
Shift+Delete forgets the whole list. It asks first — it sits
next to the key that forgets one entry, and an accidental press should not silently
discard every place you have been. datui --clear-recents does the same from the
command line.
datui --clear-cache clears everything, including measurements and query history.
Both are caches, not a catalogue. There is nothing to register, nothing to curate,
and nothing that cannot be rebuilt by looking again. datui --clear-cache removes
both, and costs only speed.
Everything else on this screen is read fresh, on a background thread, never on the one drawing the screen.
Limits
The home screen stays the same speed whether you have used datui for a day or a year. Every kind of work it does is capped:
| work | limit |
|---|---|
| recently opened paths kept | 50 |
| directories promoted to roots by a recent | the 8 most recent distinct ones |
| entries listed from one directory | 5,000 |
| subdirectories looked inside, per listing | 64 |
| files looked at to tell whether a directory is a dataset | 8 |
| files read to count the rows of a multi-file dataset | 64 |
| datasets measured at once | 12, and only ones on screen |
| network directories probed at once | 4 |
| depth of the recursive search | 8 |
| datasets a recursive search returns | 20,000 |
| wall clock for one recursive search | 1.5 s |
The caps that change what you see say so. A directory cut short reads first 5000
beside its name. A subdirectory past the 64 is still listed — it just shows as a
directory rather than as a dataset until you step into it, at which point it is
classified normally.
The two that matter most are the root cap and the subdirectory cap, because both bound round trips, which is what costs time on a network share. Fifty scattered recents once meant fifty directory listings on every rebuild; a directory of two thousand subdirectories meant roughly eighteen thousand filesystem operations to list it once. Neither is possible now.
Older places do not disappear — they stay under RECENT as individual datasets,
and any path is still reachable by typing it.
Plain terminals
On a terminal without a UTF-8 locale, datui falls back to ASCII:
  > _  type to filter

  RECENT
  > sales                        hive       2.4M x 18    340 MB    2d
Override the detection with:
[display]
unicode = "auto"    # "auto" (default), "always", or "never"
Named keys are spelled out — Enter, Tab, Bksp, Esc — matching the rest of
datui and avoiding symbols that many terminal fonts do not carry. Only the arrows are
drawn as glyphs, and they fall back with everything else.
No Nerd Font characters are used anywhere, so no patched font is needed.
Desktop launchers
datui installs /usr/share/applications/datui.desktop, so it appears in GNOME,
KDE, rofi, wofi and Omarchy’s menu under Apps. Its keywords include data,
parquet, dataframe and csv.
Launching with no file opens the home screen. The entry declares the formats datui
reads, so a file manager offers “Open with datui” for them; which application is
the default for a format stays your choice in mimeapps.list.
See Also
- Configuration —
[data] directoriesand the rest - Theming from Your System
- Loading Data — opening datasets from the command line